
H100 GPU Measured Workload Power and Thermal Profiling
H100 GPU measured workload power is the empirical quantification of electrical wattage drawn by accelerator silicon, high-bandwidth memory (HBM3), and onboard voltage regulator modules (VRMs) across varied AI computational phases. While vendor product briefs rate the NVIDIA H100 SXM5 at a static 700-watt Thermal Design Power (TDP), real-world operational power draw fluctuates dramatically depending on mathematical precision, memory bus utilization, and workload execution states. In high-density artificial intelligence data centers, deploying multi-node GPU clusters based solely on static nameplate ratings leads either to excessive infrastructure over-provisioning or catastrophic circuit breaker trips during sustained matrix multiplication bursts. Accurate thermal and power profiling is therefore essential to optimize data center cooling architectures, prevent thermal clock throttling, and maximize compute density.
Empirical Silicon Power Dissipation Across Compute Phases
Silicon Telemetry: Die, HBM3, and VRM Breakdown
Total accelerator power consumption on the SXM5 form factor represents the aggregate draw of three primary sub-systems: the GH100 processor die, the six stacks of High-Bandwidth Memory (HBM3), and the multi-phase Voltage Regulator Modules (VRMs). Under sustained FP8 Tensor Core matrix multiplication (GEMM), the GH100 silicon die accounts for approximately 510W to 540W (75% of total draw). The 80GB HBM3 memory subsystem—delivering 3.35 TB/s of bandwidth—draws 110W to 130W under full bus saturation. Onboard VRMs, which step down incoming 48V or 54V DC bus voltage to sub-1.0V core voltages at currents exceeding 700 amps, dissipate 40W to 50W as heat due to conversion inefficiencies.
Prefill vs. Autoregressive Decode Electrical Profiles
In large language model serving, computational dynamics vary sharply between operational stages. During the prefill phase, all prompt tokens are evaluated in parallel, driving Tensor Core utilization to near 100% and pushing accelerator power draw to the 700W ceiling. Conversely, during the autoregressive decode phase, single-token generation is bounded by HBM3 memory bus bandwidth rather than raw math compute. As a result, GPU power draw during decode drops to 380W–460W per GPU, despite high memory bus traffic. Infrastructure engineers must model these phase transitions to prevent false alarms in facility power threshold monitoring.
| Workload / Execution State | Arithmetic Precision | Average GPU Power (W) | Peak Transient Power (W) | Memory Bus Utilization | Typical Junction Temp (Liquid) |
|---|---|---|---|---|---|
| Idle / Static Residency | N/A | 145W | 160W | < 2% | 32°C |
| LLM Decode Phase (BS=16) | FP16 / FP8 | 420W | 480W | 88% | 48°C |
| LLM Prefill Phase (BS=64) | FP8 Tensor Core | 685W | 735W | 94% | 61°C |
| Distributed GEMM Pre-Training | BF16 Mixed | 695W | 745W | 92% | 63°C |
| High-Intensity FP8 Matrix Multiply | FP8 Native | 700W (Capped) | 760W (Transient) | 96% | 64°C |
Thermal Resistance Dynamics: Air Cooling vs. Direct Liquid Cooling
Chassis Parasitics and Thermal Resistance Curves
The heat generated by an 8-way H100 SXM5 server (5.6 kW of GPUs plus 2.5 kW of host CPUs and networking) must be rejected to prevent silicon junction temperatures ($T_j$) from reaching the 83°C thermal throttling threshold. In traditional air-cooled chassis, cooling requires aggressive counter-rotating fan modules drawing immense volumes of ambient air across dense fin arrays. Under 100% load, server fans consume between 900W and 1,300W of electrical power purely to circulate air. This parasitic fan load degrades system efficiency and creates severe acoustic noise (>85 dB).
// Thermal Resistance Equation for GPU Cooling
// T_junction = T_coolant + (Power_watts * R_thermal)
// Air Cooling: R_thermal = 0.065 °C/W
// Direct Liquid Cooling: R_thermal = 0.032 °C/W
// At 700W GPU Load with 30°C Coolant/Ambient:
// T_junction (Air)    = 30°C + (700 * 0.065) = 75.5°C (Marginal headroom to 83°C throttle)
// T_junction (Liquid) = 30°C + (700 * 0.032) = 52.4°C (Robust 30.6°C operating margin)
As demonstrated by the formulation above, direct liquid cooling cuts thermal resistance by more than half. By passing treated water-glycol coolant directly through micro-channel cold plates mounted to the GH100 lid, liquid cooling maintains GPU silicon below 55°C–65°C under maximum sustained compute loads, completely eliminating thermal throttling risks while saving over 1 kW of fan power per server node.
High-Density Power Architecture: 40 kW to 100 kW Rack Engineering
Managing Transient Power Spikes and $di/dt$ Slew Rates
A critical engineering challenge in high-density AI clusters is managing $di/dt$ current slew rates. When distributed training jobs transition simultaneously from communication barriers (AllReduce idle states) to compute-intensive forward passes, current draw across an 8-GPU server can spike by 400 amps in less than 50 microseconds. In poorly engineered facilities, these sudden inductive transients induce voltage droops that trigger server power supply unit (PSU) under-voltage lockouts. Data centers housing high-density AI clusters must deploy high-capacitance busbars and advanced power supplies with rapid transient response capabilities.
Three-Phase 480V Overhead Power Distribution
Modern AI racks housing four 8-way H100 nodes draw between 40 kW and 50 kW per rack, with next-generation Blackwell clusters exceeding 100 kW. Supplying this power at standard 208V AC requires massive copper cables that impede airflow and induce significant transmission losses ($I^2R$). Modern high-density data centers utilize 480V three-phase overhead busways stepping down directly to 48V or 54V DC at the rack level. This architecture reduces cable bulk by 70%, improves power distribution efficiency to greater than 97%, and provides modular drop cords for rapid server provisioning.
OneSource High-Density AI Infrastructure in Richardson, Texas
Purpose-Built 1.18 PUE Liquid-Cooled Facility
Retrofitting legacy enterprise data centers for high-density AI computing frequently leads to thermal bottlenecks and skyrocketing utility cooling surcharges. OneSource delivers purpose-built AI infrastructure from our flagship Tier III+ facility in Richardson, Texas, engineered specifically to support sustained 40 kW to 100 kW rack densities.
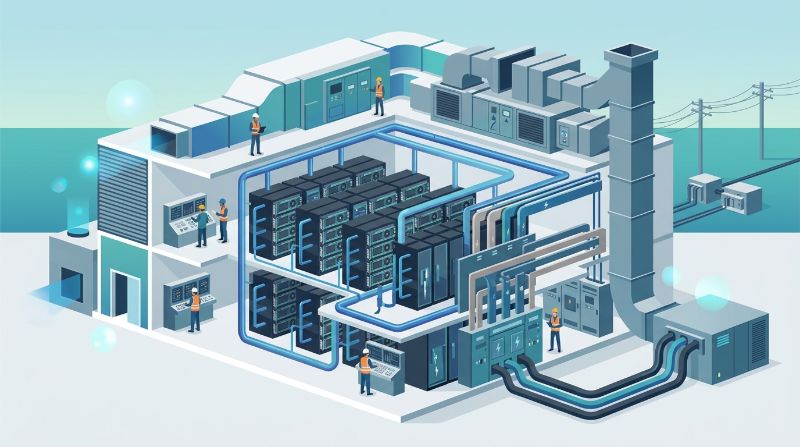
By pairing direct-to-chip liquid cooling with high-efficiency external closed-loop dry coolers, OneSource achieves an exceptional design PUE of 1.18. Even under continuous 100% FP8 matrix multiplication training runs, GPU silicon temperatures remain consistently below 65°C. This ensures GPU clocks maintain their maximum 1,980 MHz boost frequency indefinitely, delivering 100% of theoretical compute throughput without thermal throttling or hardware degradation.
Reliable ERCOT Grid Integration and Clean Busway Architecture
Located in the heart of the North Texas technology corridor, the OneSource Richardson campus features dual redundant 25 kV utility feeds connected to independent substations. Overhead 480V three-phase busways supply clean, uninterrupted electrical power to dedicated customer racks backed by high-efficiency 2N UPS systems and on-site diesel generators with 72 hours of continuous run time. Combined with low-latency dark fiber connectivity to Dallas carrier interchanges, OneSource provides the premier physical and thermal foundation for high-performance AI computing.
Frequently Asked Questions
What causes instantaneous power spikes on H100 GPU clusters?
Instantaneous power spikes are caused by synchronized transitions between collective communication steps (such as AllReduce) and matrix multiplication forward passes. When thousands of tensor cores activate simultaneously across nodes, current demand surges within microseconds, requiring high-bandwidth power delivery networks to prevent voltage dropouts.
At what temperature does the NVIDIA H100 begin thermal throttling?
The NVIDIA H100 GPU initiates thermal clock throttling at a junction temperature of 83°C, systematically stepping down boost frequencies to reduce heat dissipation. If temperatures reach 88°C, hardware thermal protections trigger an immediate emergency shutdown to prevent permanent silicon damage.
Why is direct liquid cooling superior to air cooling for 700W GPUs?
Direct liquid cooling provides a thermal transfer coefficient more than four times higher than air, maintaining GPU silicon 20°C to 25°C cooler under identical workloads. Furthermore, it eliminates internal chassis fan power draw, reducing total server electrical consumption by 10% to 15%.
Related Articles
Recommended Reading
-
How Paged Attention Manages Inference KV Cache
-
Google Cloud GPU Pricing: What Enterprise AI Teams Should Evaluate Before Provisioning
-
Paperspace Pricing 2026: GPU Cost Breakdown
-
AI Infrastructure Costs: Controlling Enterprise GPU Spending
-
CoreWeave Enterprise GPU Cloud: Evaluation for AI Teams
-
CoreWeave vs Lambda Labs vs OneSource Cloud: GPU Provider Decision Guide
-
U.S. Data Residency in the Cloud: Requirements, Regulations & Compliance Guide
-
AWS GPU Pricing: Instance Types, Cost Structure & Alternatives Guide
latest articles
-
Direct-to-Chip Liquid Cooling for AI Clusters: Facility CDUs, Secondary Loops, and Leak Detection Runbooks
-
Concurrent Request Scaling and GPU Memory Sizing in LLMs
-
LLM Retrieval Quality Monitoring Pipeline in Enterprise RAG
-
Throughput Targets and Latency Trade-offs in LLM Inference
-
LLM Inference Cost per GPU Hour and Token Economics
-
GPUDirect Storage vs CPU Bounce Buffers: DMA Bypass, PCIe Topology, and High-Throughput AI I/O
-
GPU Requirements for Production LLM Inference Workloads
-
Disaggregated Prefill and Decode for Enterprise LLMs: KV Cache RDMA Transfer, TTFT, and Serving Economics
-
Distributed Training Encryption Policy for Enterprise AI
-
H100 Server Electricity Cost Model for High-Density AI